How to Remove Duplicate PDF Pages
How duplicates get into PDFs, how detection works, and what to watch out for before deleting
Duplicate pages in PDFs are almost always accidental. A scanner jams and restarts, picking up three pages that were already scanned. Two PDFs get merged with overlapping page ranges. Someone copies a block of pages into a document twice and doesn't notice until the file is already 80 pages long. The result is bloated files, confused readers, and sometimes corrupted page numbering.
Removing duplicates is lossless - pages are deleted from the file structure without any modification to remaining content. But the process has some genuine gotchas, particularly around near-duplicates and pages that look identical but aren't. This guide covers how detection works, what can go wrong, and how to be confident you're only removing what you intend to.
Watch: How to Remove Duplicate PDF Pages with PDFHaul (step-by-step walkthrough)
How Duplicate Pages Get Into PDFs
Understanding the source of duplicates helps you know what kind of detection to apply. The causes fall into three categories:
Scanning errors
The most common cause. Auto-document feeders are reliable but not perfect. When a jam occurs mid-batch and the operator restarts the scan, the restart typically overlaps by a few pages to make sure nothing was missed. Those pages then appear twice in sequence. Double-feed incidents (where two pages go through together and the scanner detects something is wrong, then rescans) produce the same result. The duplicates are usually adjacent in the document, making them easy to spot visually.
Merge mistakes
Merging two PDFs with overlapping page ranges is a surprisingly easy mistake. If you merge pages 1-50 from Document A with pages 45-100 from Document B because both cover the same project period, pages 45-50 appear twice. These duplicates may not be adjacent, and they may have different metadata (creation timestamps, producer software) even if the visible content is identical, which affects how detection tools find them.
Assembly and copy-paste errors
When assembling a PDF from pieces - inserting pages from multiple sources, copying sections - it's easy to paste the same block twice. These duplicates are usually exact copies and easy to detect automatically. The harder case is when two separately created pages have the same content (a standard cover page, a company disclaimer, a signature block that appears in multiple documents that were merged).
How Duplicate Detection Actually Works
Most tools, including PDFHaul, detect duplicates using content hashing: a digital fingerprint is generated for each page based on its content, dimensions, and structure. Pages with identical fingerprints are flagged as duplicates. This approach is fast and accurate for exact duplicates.
The key distinction is between exact and near duplicates:
Exact duplicates are byte-for-byte identical. Same text, same images, same formatting, same dimensions. Content hashing catches these reliably. This covers most scanning restarts, paste errors, and digital merge overlaps where both copies came from the same source file.
Near duplicates look identical but have minor differences beneath the surface: different creation timestamps, different embedded metadata, slightly different image compression from being exported through different software. Two pages from the same original document that were scanned at different times may be visually indistinguishable but won't match on a hash comparison. Detecting these requires visual rendering comparison, which is slower and more resource-intensive.
Similar but distinct pages share structure or layout but have different content: a recurring header page, a standard form that appears multiple times with different fields filled in, pages from a template. These should not be removed. Aggressive detection settings that lower the similarity threshold can mistakenly flag these as duplicates.
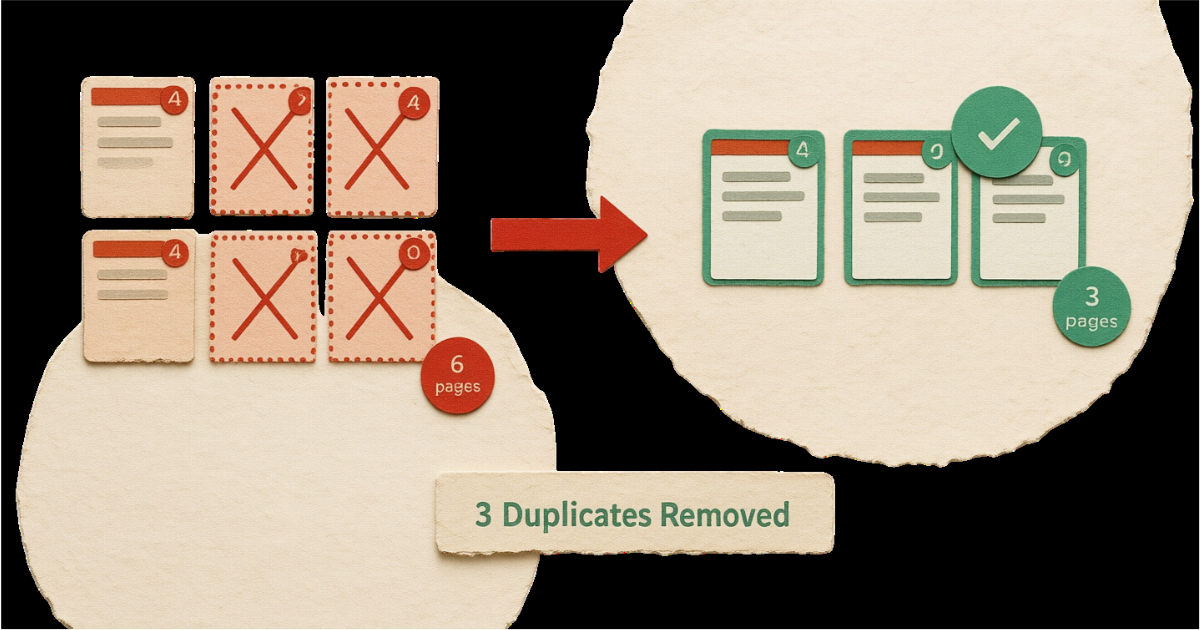
PDFHaul uses content hash comparison by default, which catches exact duplicates reliably and avoids false positives on pages that are merely similar. The first instance of each duplicate is preserved; subsequent copies are removed.
Cases Where You Should Review Before Deleting
Most duplicate removal is straightforward. These are the situations that warrant a closer look:
Pages that are intentionally repeated
Some documents repeat content on purpose: safety instructions at the start of each chapter, a terms and conditions page that precedes each section, a cover sheet that appears at the beginning of each attachment in a merged filing. Automatic detection will flag these as duplicates. Review the flagged pages in context before deleting.
Version differences on near-identical pages
A common scenario in legal and financial documents: an original version of a clause and a revised version exist in the same PDF, merged from two draft stages. If the revision is minor (a date change, a number update, a single word), visual inspection might miss it. Before removing near-duplicates, zoom to 100% and compare the flagged pages side by side. The difference that looks minor may be exactly the content that matters.
Scanned pages with quality variation
Two scanned copies of the same original page won't be byte-identical. The scan quality, angle, brightness, and compression all vary slightly between passes. Automatic detection may miss these as duplicates entirely (they don't hash-match), or near-duplicate detection may flag them. If you're cleaning up a scan, check the flagged pages manually to confirm they're truly duplicating content, not capturing different originals.
Template and form pages
Standard forms, cover pages, and template pages that appear multiple times in a merged document are legitimate duplicates in most cases. But if the form has been filled out differently each time it appears, removing the duplicates would delete real data. Always check whether the flagged pages have different field content before deleting.
How to Remove Duplicate Pages with PDFHaul
PDFHaul's remove duplicates tool analyzes page content, dimensions, and structure to identify identical pages automatically. No manual configuration is required for standard use.
Upload your PDF. Files up to 100MB are supported. Password-protected PDFs need to be unlocked first.
Let the detection run. PDFHaul generates a content fingerprint for each page and identifies matches. For a typical business document this takes a few seconds. Larger scanned documents take longer due to the volume of image data.
Review the flagged pages. Before confirming deletion, look at the pages identified as duplicates. Confirm they're actually redundant rather than similar-but-distinct content. This step is especially important for legal documents, filled forms, and any document where near-identical pages might have meaningful differences.
Remove and download. Click Remove Duplicates. The cleaned PDF downloads immediately. The first instance of each duplicate is kept; all subsequent copies are removed. Page order is preserved.
Always keep your original PDF until you've confirmed the cleaned version is correct. Download and open the result before deleting your backup.
What Changes in Your Document After Removal
Removing duplicate pages has a few downstream effects worth knowing about:
Page numbers shift. If your document has a table of contents or internal cross-references like 'see page 14,' those references will be wrong after removal. Scan the document for page number citations and update them, or add a note that the TOC reflects the pre-cleanup page numbering.
File size decreases. The reduction depends on how many pages are removed and how image-heavy they are. Text-only pages are relatively small (50-200KB each). Scanned pages are much larger (500KB-2MB each). Removing 10 scanned duplicates from a 200-page document can reduce file size by 5-20MB.
Bookmarks may need updating. If the document had bookmarks pointing to pages that were removed, those bookmarks will now be broken. Bookmarks pointing to pages that shifted position should update automatically, but verify in a PDF reader after downloading.
Page count changes. If you're submitting the document to a system that expects a specific page count (a court filing, a submission form), confirm the new count meets requirements before sending.
Combining Duplicate Removal with Other Cleanup Steps
Duplicate removal is usually one step in a broader cleanup workflow, particularly for scanned documents or merged PDFs. A logical sequence:
Remove duplicates first. Eliminate redundant pages before doing anything else. This reduces the total page count and makes subsequent steps faster.
Remove empty or blank pages. Scanning often produces blank pages from the back of single-sided originals. Use PDFHaul's remove empty pages tool as the next step.
Reorder if needed. If the duplicate removal changed your page sequence in an unexpected way, reorder pages before finalizing.
Compress. Once the page count is final, run compression to reduce file size further. Compressing after removing pages is more efficient than compressing before, since you're only processing the pages that will actually be in the final document.
Preventing Duplicate Pages from the Start
A few habits eliminate most duplicate page problems before they happen:
When restarting a scan after a jam, note the last successfully scanned page number and restart from there, not a few pages back. Restarting conservatively to be safe is the main source of scan duplicates.
When merging PDFs, write down the page ranges you're including from each source before merging. Explicit range planning prevents overlap.
Review merged documents immediately after combining them rather than distributing first and cleaning up later. Duplicates are much easier to spot when the merge is fresh.
For high-volume scanning workflows, enable duplicate detection in your scanner software if it supports it. Many document scanner apps (Fujitsu ScanSnap, Canon IJ Scan, ABBYY FineReader) have built-in duplicate page detection.
When inserting pages into an existing document, scroll through the area around the insertion point afterward to confirm the pages appear exactly once.
Troubleshooting
Duplicates weren't detected
If you know a document has duplicate pages but none were flagged, the copies likely have minor metadata differences (different timestamps, different producer software) that prevent a hash match. This is common when duplicates came from two different scan passes or two different export operations. Try a visual comparison approach if your tool supports it, or identify the duplicate page range manually and use the page removal tool to delete specific pages by number.
Non-duplicate pages were flagged
This is a false positive, usually from template or form pages that have identical structure. Review flagged pages carefully before confirming deletion. If the tool offers a sensitivity setting, increasing the required match percentage reduces false positives at the cost of potentially missing near-duplicates.
The document has duplicates but also intentional repetition
Disable automatic deletion and review each flagged page individually. Confirm whether repeated pages are true duplicates (an error) or intentional (a deliberate design choice like repeated safety warnings). Delete only the confirmed errors.
After removal, the document seems to be missing content
This means a page was removed that shouldn't have been. Restore from your original backup (this is why keeping the original until you've verified the cleaned version matters), review the removal more carefully, and re-run with higher sensitivity settings or manual review.
Frequently Asked Questions
Will removing duplicates affect the quality of remaining pages?
No. Duplicate removal only deletes redundant copies. The content, images, fonts, and resolution of pages that remain in the document are completely unchanged.
Which copy of a duplicate page is kept?
By default, the first instance is preserved and all subsequent copies are removed. The first instance is usually the correct one for documents assembled in order.
How does PDFHaul tell the difference between duplicate pages and similar-but-different pages?
PDFHaul uses content hashing: a fingerprint generated from each page's content, dimensions, and structure. Only pages with identical fingerprints are flagged. Pages with even small differences in content produce different fingerprints and won't be flagged.
Can I undo the removal if I deleted the wrong pages?
Not directly. Once you've downloaded the cleaned PDF, the operation is final. This is why keeping your original PDF until you've reviewed the cleaned version is important. If you deleted the wrong pages, restore from the original and run the process again with more careful review.
Will the tool remove pages that look identical but were created at different times?
If the pages are byte-identical (same content, same metadata), yes. If they differ in metadata (different creation timestamps, different scan passes) but look the same visually, standard hash-based detection won't catch them. These need visual comparison tools or manual identification.
How much will my file size decrease?
It depends on the number of duplicates and their content. Text-only pages save roughly 50-200KB each. Scanned page duplicates save 500KB-2MB each. A document with 15 scanned duplicate pages could shrink by 7-30MB.
Ready to clean up your PDF? Try PDFHaul's duplicate removal tool - free, no account required, files deleted automatically after 2 hours.
Peter
Founder of PDFHaul and Bultech
Building tools that make working with documents faster and simpler.